<?php include '../../../commonheader.php'; ?>

<div id="wrap">
  <div id="main">
    <h1>ImageNet Large Scale Visual Recognition Challenge 2013 (ILSVRC2013)</h1>

    <div id="about_content" class="aboutoverview">

      <a href="./index#introduction">Introduction</a> &nbsp;
      <a href="./index#introduction">History</a> &nbsp;
      <a href="./index#data">Data</a> &nbsp;
      <a href="./index#task">Tasks</a> &nbsp;
      <!--<a href="#devkit">Development kit</a> &nbsp;-->
      <a href="./index#timetable">Timetable</a> &nbsp;
      <!--<a href="#features">Features</a> &nbsp-->
      <!--<a href="submission">Submission</a> &nbsp;-->
      <a href="./index#cite">Citation</a><sup><font color='red'>new</font></sup> &nbsp;
      <a href="./index#organizers">Organizers</a> &nbsp;
      <!--<a href="index#advisors">Advisors</a> &nbsp;-->
      <a href="./index#sponsors">Sponsors</a> &nbsp;
      <a href="./index#contact">Contact</a> &nbsp;
      <!--<a href="index#workshop">Workshop</a> &nbsp-->
      <!--<a href="signup">Download</a> &nbsp-->
      <!--<a href="test_server">Evaluation Server</a>-->
      <!--<a href="#testing">Testing</a> &nbsp-->
      <!--<a href="#publicationpolicy">Publication policy</a>&nbsp-->
      <!--<a href="#citation">Citation</a> &nbsp-->
      <!--<a href="#rights">Database rights</a> &nbsp-->
          
      <h2>News</h2>
      <ul>
      <li>September 2, 2014:  <a href="#cite">A new paper</a> which describes the collection of the ImageNet Large Scale Visual Recognition Challenge dataset, analyzes the results of the past five years of the challenge, and even compares current computer accuracy with human accuracy is now available. <i>Please cite it, along with the original ImageNet paper, when reporting ILSVRC2013 results or using the dataset.</i>
      <li> February 21, 2013: <a href="#">ILSVRC 2013 automated test server</a> is available.
      <!--<li> February 8, 2013: The test server is temporarily unavailable, we apologize for the inconvenience.
      <li> December 23, 2013: <a href="./test_server">ILSVRC 2013 automated test server</a> is available.
      <li> December 23, 2013: ILSVRC 2013 automated test server is available.-->
      </li><li>November 14, 2013: <a href="./results.php">ILSVRC 2013 results</a> are available! Details about the methods coming up at the <a href="./iccv2013.php">ICCV 2013 workshop</a>.
      </li><li>November 11, 2013: Submission site is up. Please submit your results <a href="./submission.php">
         here</a>. (See <a href="./faq.php">FAQ</a> for details.)
      </li><li>September 19, 2013: <a href="./iccv2013.php">ICCV 2013 workshop</a> page is up.
      </li><li>August 15, 2013: The development kit and data are released. 
      </li><li>July 15, 2013: Registration page is up. Please <a href="#">register</a><a> 
      </a></li><li>March 18, 2013: We are preparing to run the ImageNet Large Scale Visual Recognition Challenge 2013 (ILSVRC2013). Stay tuned! 
      </a></li><li>March 18, 2013: The new<a href="https://sites.google.com/site/fgcomp2013/">Fine-Grained Challenge 2013</a> will run concurrently with ILSVRC2013.
      </li>
      </ul>


      <p><a name="introduction"><h2>Introduction</h2></a></p>

      This challenge evaluates algorithms for object detection and image classification at large scale. This year there will be three competitions: 
      <ol>
      <li> A <a href="http://pascallin.ecs.soton.ac.uk/challenges/VOC/">PASCAL-style</a> detection challenge on fully labeled data for 200 categories of objects,<sup><font color="red"><b>NEW</b></font></sup> </li>
      <li> An image classification challenge with 1000 categories, and </li>
      <li> An image classification plus object localization challenge with 1000 categories. </li> 
      </ol>
      One high level motivation is to allow researchers to compare progress in detection across a wider variety of objects -- taking advantage of the quite expensive labeling effort. 
      Another motivation is to measure the progress of computer vision for large scale image indexing for retrieval and annotation.

      <!--
      <p>
      More information is available on the webpage for last year's competition here:
      <ul>
      <li>
      <a href="../2012/index.php"> ILSVRC 2012 </a>.
      </li>
      </ul>
      -->

      <p><a name="history"><h2>History</h2></a></p>
      <ul>
      <li> <a href="../2012/index.php"> ILSVRC 2012 </a> </li>
      <li> <a href="../2011/index.php"> ILSVRC 2011 </a> </li>
      <li> <a href="../2010/index.php"> ILSVRC 2010 </a> </li>
      </ul>


      <p><a name="data"><h2>Data</h2></a></p>

      <p><a><h3>Dataset 1: Detection</h3></a></p>
      <br clear="all">
      This year there is a new object detection task similar in style to
      <a href="http://pascallin.ecs.soton.ac.uk/challenges/VOC/"> PASCAL VOC
      Challenge</a>. There are <a href="./browse-det-synsets.php">200 basic-level categories</a> for
      this task which are fully annotated on the test data, i.e. bounding
      boxes for all categories in the image have been labeled. The categories
      were carefully chosen considering different factors such as object
      scale, level of image clutterness, average number of object instance,
      and several others. Some of the test images will contain
      none of the 200 categories.  

      <p style="text-align:center"><b>Comparative scale</b></p>

      <table border="1" cellpadding="5" align="center">
      <tbody><tr>
      <td colspan="2"></td>
      <td style="text-align:center"> <a href="http://pascallin.ecs.soton.ac.uk/challenges/VOC/voc2012/">PASCAL VOC 2012</a> 
      </td>
      <td style="text-align:center"> ILSVRC 2013</td>
      </tr>

      <tr>
      <td colspan="2"> Number of object classes </td>
      <td style="text-align:center">20</td>
      <td style="text-align:center"><b>200</b></td>
      </tr>

      <tr>
      <td rowspan="2"> Training </td>
      <td style="text-align:center"> Num images </td>
      <td style="text-align:center">5717</td>
      <td style="text-align:center">395909</td>
      </tr>

      <tr>
      <td style="text-align:center"> Num objects </td>
      <td style="text-align:center">13609</td>
      <td style="text-align:center">345854</td>
      </tr>

      <tr>
      <td rowspan="2">Validation </td>
      <td style="text-align:center"> Num images </td>
      <td style="text-align:center">5823</td>
      <td style="text-align:center">20121</td>
      </tr>

      <tr>
      <td style="text-align:center"> Num objects </td>
      <td style="text-align:center">13841</td>
      <td style="text-align:center">55502</td>
      </tr>

      <tr>
      <td rowspan="2"> Testing </td>
      <td style="text-align:center"> Num images </td>
      <td style="text-align:center">10991</td>
      <td style="text-align:center">40152</td>
      </tr>

      <tr>
      <td style="text-align:center"> Num objects </td>
      <td style="text-align:center">---</td>
      <td style="text-align:center">---</td>
      </tr>

      </tbody></table>

      <p style="text-align:center"><b>Comparative statistics (on validation set)</b></p>

      <table border="1" cellpadding="5" align="center">
      <tbody><tr>
      <td></td>
      <td style="text-align:center"> <a href="http://pascallin.ecs.soton.ac.uk/challenges/VOC/voc2012/">PASCAL VOC 2012</a> 
      </td>
      <td style="text-align:center"> ILSVRC 2013</td>
      </tr>

      <tr>
      <td style="text-align:center">Average image resolution </td>
      <td style="text-align:center">469x387 pixels</td>
      <td style="text-align:center">482x415 pixels</td>
      </tr>

      <tr>
      <td style="text-align:center"> Average object classes per image </td>
      <td style="text-align:center">1.521</td>
      <td style="text-align:center">1.534</td>
      </tr>

      <tr>
      <td style="text-align:center"> Average object instances per image</td>
      <td style="text-align:center">2.711</td>
      <td style="text-align:center">2.758</td>
      </tr>

      <tr>
      <td style="text-align:center"> Average object scale <br>(bounding box area as fraction of image area)</td>
      <td style="text-align:center">0.207</td>
      <td style="text-align:center">0.170*</td>
      </tr>

      </tbody></table>
      <font size="1">* has been corrected from previous version</font>

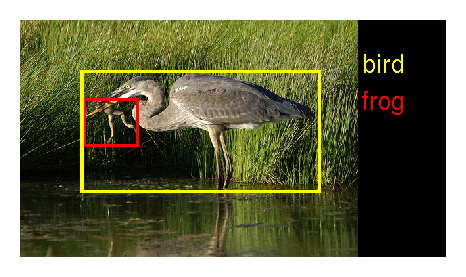
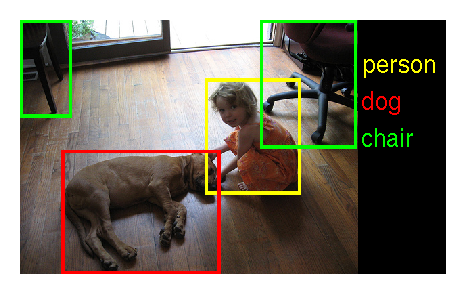
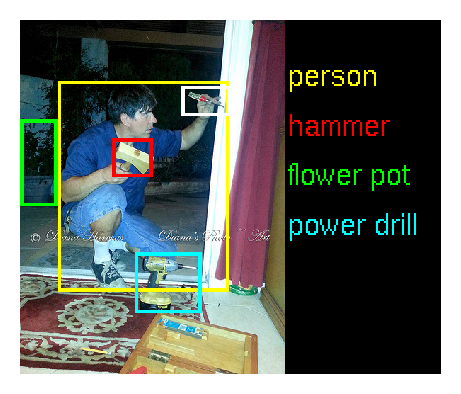
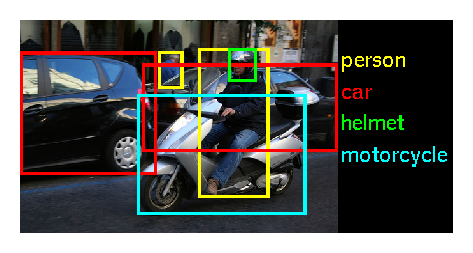
      <p> Example ILSVRC2013 images:

      <table align="center">
      <tbody><tr>
      <td style="text-align:center">
      <img height="180" src="/static_files/figures/ILSVRC2012_val_00004945.png">
      </td>
      <td style="text-align:center">
      <img height="180" src="/static_files/figures/ILSVRC2012_val_00042692.png">
      </td>
      </tr><tr>
      <td style="text-align:center">
      <img height="180" src="/static_files/figures/ILSVRC2013_val_00003169.png">
      </td>
      <td style="text-align:center">
      <img height="180" src="/static_files/figures/ILSVRC2012_val_00004465.png">
      </td>
      </tr>
      </tbody></table>

      </p><ul>
      <li><a href="#"> Browse the 200 detection categories here</a>.
      </li></ul>

      <p> Note: people detection on ILSVRC2013 may be of particular
      interest. There are 12125 images for training (9877 of them contain
      people, for a total of 17728 instances), 20121 images for validation
      (5756 of them contain people, for a total of 12823 instances) and
      40152 images for testing.  There is significant variability in pose
      and appearance, in part due to interaction with a variety of
      objects. In the validation set, people appear in the same image with
      196 of the other labeled object categories.

      <a></a><p><h3><a>Dataset 2: Classification and classification with localization</a></h3></p>
      <br clear="all">

      <p> The data for the classification and classification with localization tasks will remain unchanged from <a href="../2012/index.php"> ILSVRC 2012 </a>. The validation and test data  will consist of 150,000 photographs, collected from flickr and other search engines, hand labeled with the presence or absence of <a href="./browse-synsets.php">1000 object categories</a>. 
      The 1000 object categories contain both internal nodes and leaf nodes of ImageNet, but do not overlap with each other. 
      A random subset of 50,000 of the images with labels will be released as validation data included in
      the development kit along with a list of the 1000 categories.  The remaining images will be used 
      for evaluation and will be released without labels at test time.  

      </p><p> The training data, the subset of ImageNet containing the 1000 categories and 1.2 million images, 
       will be packaged for easy downloading.  The validation and test data for this competition are
       not contained in the ImageNet training data.
      </p><ul>
      <li><a href="./browse-synsets.php"> Browse the 1000 classification categories here</a>.
      </li></ul>


      <p><a name="task"><h2>Tasks</h2></a></p>

      <h3>Task 1: Detection <sup><font color="red">NEW</font></sup> </h3>
      <br clear="all">

      For each image, algorithms will produce a set of annotations $(c_i, b_i, s_i)$ of class labels 
         $c_i$, bounding boxes $b_i$
         and confidence scores $s_i$. This set is expected to contain each instance of each of the 200 object categories. Objects which were not annotated will be penalized, as will be duplicate detections (two annotations for the same object instance). 
      The winner of the detection challenge will be the team which achieves
      first place accuracy on the most object categories.

      <!--The complete labeling will be evaluated using the mean average precision metric as in <a href="http://pascallin.ecs.soton.ac.uk/challenges/VOC/">PASCAL VOC Challenge</a>.-->
      <br clear="all">
      <br clear="all">

      <h3>Task 2: Classification and localization</h3>

      <br clear="all">
      <p>

         In this task, given an image an algorithm will produce 5 class labels $c_i, i=1,\dots 5$ in decreasing order of confidence and 5
         bounding boxes $b_i, i=1,\dots 5$, one for each class label. The quality of a
      labeling will be evaluated based on the label that best matches the
      ground truth label for the image. The idea is to allow an algorithm to
      identify multiple objects in an image and not be penalized if one of
      the objects identified was in fact present, but not included in the
      ground truth.

      </p><p>
      The ground truth labels for the image are 
      															   $C_k, k=1,\dots n$
      															   with $n$ class labels. For each ground truth class label $C_k$, the ground truth bounding boxes are $B_{km},m=1\dots M_k$, where $M_k$ is the number of instances
      															   of the $k^\text{th}$ object in the current image.

      </p><p>
      															   Let $d(c_i,C_k) = 0$ if $c_i = C_k$ and 1 otherwise. Let $f(b_i,B_k) = 0$ if $b_i$ and $B_k$ have more than $50\%$ overlap, and 1 otherwise. The error of the algorithm on an individual image will be computed using two metrics:

      </p><ul>
      <li>Classification-only:
      \[ e= \frac{1}{n} \cdot \sum_k \min_i d(c_i,C_k) \]

      		       </li><li>Classification-with-localization:
      \[ e=\frac{1}{n} \cdot \sum_k min_{i} min_{m}  max \{d(c_i,C_k), f(b_i,B_{km}) \} \]
      </li></ul>

      The classification-only and classification-with-localization errors of the algorithm is the average corresponding error across all test images.


      <h2>Development Kit</h2>

      <ul>
      <p><a href="http://imagenet.stanford.edu/image/ilsvrc2013/ILSVRC2013_devkit.tgz">Development kit <img src="./download_button.jpg" width="16px" height="16px"></a> (updated Aug 24, 2013)<br>
      Please be sure to consult the included readme.txt file for competition details. Additionally, the development kit includes
      </p><ul>
      <li>Overview and statistics of the data.</li>
      <li>Meta data for the competition categories.</li>
      <li>Matlab routines for evaluating submissions.</li>
      </ul>
      <p> Please <a href="./signup">register</a><a> to obtain the download links for the data.
      </a></p></ul><a>

      </a><p><a name="timetable"><h2>Timetable</h2></a></p>
      <ul> 
      <li> August 15, 2013: Development kit, data and evaluation software made available. </li> 
      <li> November 15, 2013: Submission deadline. </li>
      <li> November 22, 2013: Extended deadline for updating the submitted entries
      (details in <a href="./faq.php">FAQ</a>).</li>
      <li> December 7, 2013: <a href="./iccv2013.php">ImageNet Large Scale Visual Recognition
      Challenge 2013 workshop</a> at <a href="http://www.iccv2013.org/workshops.php">ICCV 2013</a>. 
      Challenge participants with the most successful and innovative methods will be invited to present.
      </li></ul>

      <p><a name="submission"><h2>Submission</h2></a></p>

      Please submit your results <a href="./submission.php">
      here</a>, and refer to the <a href="./faq.php">FAQ</a> for details.

      <p><a name="cite"><h2>Citation<sup><font color="red">NEW</font></sup></h2></a></p>
If you are reporting results of the challenge or using the dataset, please cite <b>both</b> of the following papers (as the challenge and dataset depend on contributions from both papers):
      <ul>Jia Deng, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, Li Fei-Fei. <b>Imagenet: A Large-Scale Hierarchical Image Database</b>. <i>CVPR</i> 2009.
      <a class="brightlink" href="https://image-net.org/static_files/papers/imagenet_cvpr09.bib">bibtex</a>
      </ul>
      <ul>
          Olga Russakovsky*, Jia Deng*, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bernstein, Alexander C. Berg and Li Fei-Fei. (* = equal contribution) <b> ImageNet Large Scale Visual Recognition Challenge</b>. <i>IJCV,</i> 2015.
      <a class="brightlink" href="http://link.springer.com/article/10.1007/s11263-015-0816-y?sa_campaign=email/event/articleAuthor/onlineFirst#">paper</a> |
      <a class="brightlink" href="http://ai.stanford.edu/~olga/bibtex/ILSVRC15.bib">bibtex</a> |
      <a class="brightlink" href="http://arxiv.org/abs/1409.0575">paper content on arxiv</a>
      </ul>


      <p><a name="organizers"><h2>Organizers</h2></a></p>
      <ul>
        <li>Olga Russakovsky ( Stanford University )</li>
      	<li>Jia Deng ( Stanford University )</li>
        <li>Jonathan Krause ( Stanford University )</li>
      	<li>Alex Berg ( UNC Chapel Hill )</li>
      	<li>Fei-Fei Li ( Stanford University )</li>
      </ul>

      <p><a name="advisors"><h2>Advisors</h2></a></p>
      <ul>
      <li> Alexei Efros ( CMU ) </li>
      <li> Derek Hoiem ( UIUC ) </li>
      <li> Jitendra Malik ( UC Berkeley ) </li>
      <li> Chuck Rosenberg ( Google ) </li>
        <li>Andrew Zisserman ( University of Oxford ) </li>
      </ul>

      <p><a name="sponsors"><h2>Sponsors</h2></a></p>
      <ul>
      <img src="/static_files/figures/stanford-logo.png" height="75">
      &nbsp; &nbsp;
      <img src="/static_files/figures/unc.jpeg" height="65">
      &nbsp; &nbsp;
      <img src="/static_files/figures/google.jpeg" height="55">
      </ul>

      <p><a name="contact"><h2>Contact</h2></a></p>
      Please feel free to send any questions or comments to <a href="mailto:imagenet.help.desk@gmail.com">imagenet.help.desk@gmail.com</a><a href="mailto:ilsvrc2013@image-net.org">ilsvrc2013@image-net.org</a>.
    </div><!--/about_content-->
  </div>  <!--/main-->
</div><!--/wrap-->

<br clear="all">

<?php include '../../../commonfooter.php'; ?>